Video-text pretraining

Advancing Video-Text Pretraining with Multi-View Captions

Fida Mohammad Thoker1,†, Renaud Vandeghen2,†, Karen Sanchez1, Marc Van Droogenbroeck2, Bernard Ghanem1
1 King Abdullah University of Science and Technology (KAUST) 2 University of Liège

† Equal contribution

10Mvideos recaptioned
2caption granularities
3supervision stages

Abstract

Video-text pretraining with richer language supervision

Video-text pretraining has advanced through larger models and datasets, yet the quality of language supervision remains underexplored. Existing web-scale datasets often provide only one sparse caption per video, while captioning models can introduce unsupported details. We propose a large-scale multimodal language-model framework that creates complementary summary and detailed captions, refines detailed descriptions through visual reasoning, and adds semantically positive captions. To use these views effectively, we introduce separate CLS tokens for summary and detailed text. Across standard, fine-grained, and detailed text-to-video retrieval benchmarks, MVC consistently improves zero-shot and fine-tuned performance while using smaller pretraining corpora than existing approaches.

From one caption to several views

One video, richer supervision

A single source caption can miss the actions and context in a clip. MVC keeps a concise summary alongside a refined detailed description and a semantically focused positive caption.

Outdoor cooking19.9 seconds
Original · one caption

a boy preparing food in a large pot

MVC summary

The boy prepares a dish by pouring oil into a wok and adding chopped green onions.

Refined detailed caption

A young boy in a red shirt and black shorts stands in an outdoor kitchen. He pours oil from a jar into a large wok over a fire, then walks to a wooden table, picks up a plate with chopped onions and green vegetables, and adds them to the wok. The setting includes various cooking tools, a yellow basket, and greenery in the background.

Semantic positive

The boy pours yellow liquid from a glass jar into the large metal wok, resulting in the liquid collecting in the bottom of the wok as it begins to heat on the fire.
Bocce game10.8 seconds
Original · one caption

two old ladies playing bocce

MVC summary

A woman in a blue sweater throws a ball and walks forward, while others prepare to throw more balls in an outdoor game.

Refined detailed caption

The video shows a group of people playing bocce ball on an outdoor paved court. The game involves throwing balls toward a target ball. One individual throws a ball, then walks away. Other people are present in the background, some standing and walking. The setting includes a white building with columns, steps, and windows, along with grass and other structures. Players are dressed in casual clothing.

Semantic positive

The woman in the pink cap and blue jacket releases a metal ball from her right hand, causing it to roll across the paved surface and come to rest near other scattered metal balls on the ground.

Examples are from 10–20 second clips in InternVid-10M-FLT. MVC also creates a second summary and detailed caption, then generates additional positive views for training.

Captioning pipeline

Generate, verify, and diversify captions

MVC builds complementary language supervision for each video, then trains the text encoder to represent summary and detailed descriptions separately.

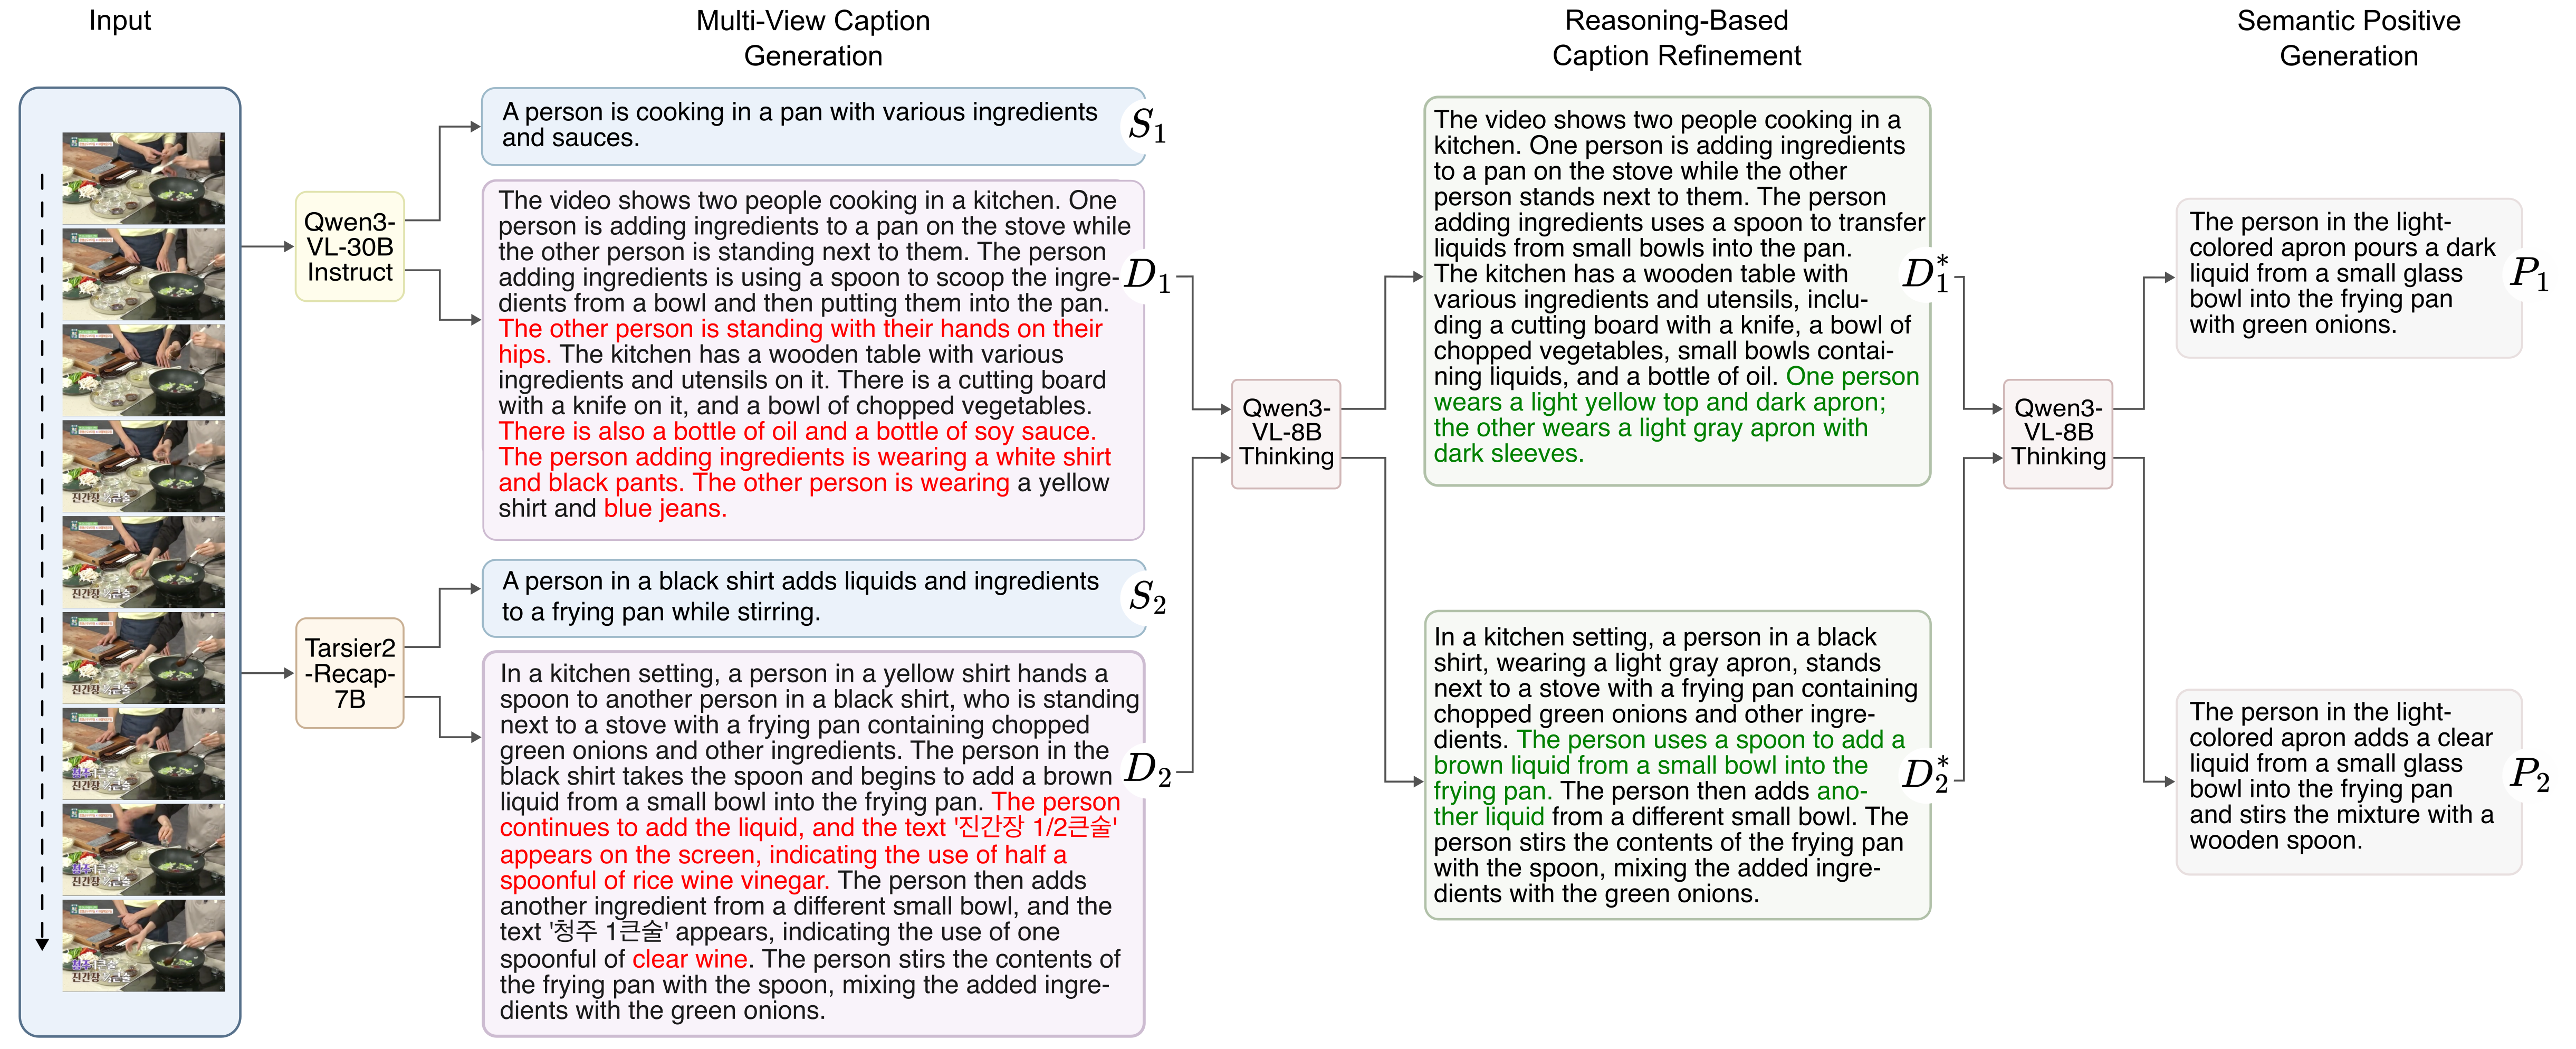
MVC pipeline: two video captioning models generate summary and detailed descriptions; a reasoning model refines detailed captions; and semantic positive captions are generated from the verified descriptions.
Two captioning models create summary and detailed views. Visual reasoning corrects unsupported details, and semantic positives describe other grounded aspects of the clip.
01

Multi-view captions

Tarsier2-Recap-7B and Qwen3-VL-30B-Instruct produce concise summaries and detailed descriptions.

02

Visual refinement

Qwen3-VL-8B-Thinking checks detailed captions against the video and removes unsupported claims.

03

Semantic positives

Additional captions shift attention to other visible actions or objects while staying grounded in the same clip.

Granularity-aware text representations

Two CLS tokens for two caption views

MVC assigns a separate CLS token to summary captions and to refined detailed or semantic positive captions. Each view uses video-text contrastive learning (VTC), video-text matching (VTM), and masked language modeling (MLM), while sharing the same video representation.

2

Dual CLS · MVC

Each caption granularity gets its own token.

Summary
\(\{O,S_1,S_2\}\)
\(\texttt{[CLS]}_s\)
\(\mathcal{L}^{s}\)
Detailed
\(\{D_1^{*},D_2^{*},P_1,P_2\}\)
\(\texttt{[CLS]}_d\)
\(\mathcal{L}^{d}\)
\[ \begin{aligned} \mathcal{L}^{s} &= \mathcal{L}_{\mathrm{VTC}}^{s} + \mathcal{L}_{\mathrm{VTM}}^{s} + \mathcal{L}_{\mathrm{MLM}}^{s}, \\ \mathcal{L}^{d} &= \mathcal{L}_{\mathrm{VTC}}^{d} + \mathcal{L}_{\mathrm{VTM}}^{d} + \mathcal{L}_{\mathrm{MLM}}^{d}. \end{aligned} \] \[ \mathcal{L} = \frac{1}{2}\left(\mathcal{L}^{s}+\mathcal{L}^{d}\right). \]

Both views use the same video representation; their losses are averaged.

Summary captions capture the main event in a few words; detailed captions describe actors, objects, and action order. Separate CLS tokens let the text encoder learn a representation suited to each granularity, while both views remain aligned with the same video. This gives the model room to preserve complementary summary and detailed information.

For each video, MVC samples one summary caption and one refined detailed or semantic positive caption and applies the corresponding view-specific loss to each.

Results

Baseline and MVC results at 5M and 10M

The tables below reproduce the paper's standard zero-shot, fine-tuned, and fine-grained zero-shot results. Baseline-B uses original captions; MVC uses multi-view captions. The 10M rows are emphasized. All scores are Recall@1; higher is better.

Table 1 · Standard zero-shot retrieval

Zero-shot text-to-video retrieval (R@1)
Model Samples MSR-VTT DiDeMo ActivityNet LSMDC MSVD
Baseline-B original captions5M34.232.729.611.139.1
MVC-B (Ours)5M38.258.958.618.143.3
MVC-L (Ours)5M40.661.263.921.048.4
MVC-B (Ours)10M39.061.061.018.644.2
MVC-L (Ours)10M41.162.066.924.149.0

Baseline-B uses original InternVid captions. MVC rows use InternVid-10M-FLT with multi-view captions; 5M and 10M denote the pretraining subset size.

Table 2 · Fine-tuned retrieval

Fine-tuned text-to-video retrieval (R@1)
Model Samples MSR-VTT DiDeMo ActivityNet LSMDC MSVD
Baseline-B original captions5M48.061.255.731.145.0
MVC-B (Ours)5M50.372.964.434.146.0
MVC-L (Ours)5M55.581.372.143.253.8
MVC-B (Ours)10M52.874.865.235.250.1
MVC-L (Ours)10M58.182.975.245.655.8

Baseline-B uses original InternVid captions. MVC rows use InternVid-10M-FLT with multi-view captions; 5M and 10M denote the pretraining subset size.

Table 3 · Fine-grained zero-shot retrieval

Fine-grained and detailed text-to-video retrieval (R@1)
Model Samples CaRe-S CaRe-T DREAM-D DREAM-E S2S-W S2S-S
Baseline-B original captions5M51.229.659.518.562.444.4
MVC-B (Ours)5M89.460.194.129.194.473.5
MVC-L (Ours)5M90.966.895.733.196.076.4
MVC-B (Ours)10M90.660.994.530.195.275.0
MVC-L (Ours)10M92.967.496.433.696.477.3

CaRe-S/T = CaReBench spatial/temporal; DREAM-D/E = DREAM-1K detailed/events; S2S-W/S = Shot2Story whole-clip/single-shot. Baseline-B uses original captions; MVC uses multi-view captions.